See what your agents are actually doing.

Change one base URL and vessel captures every LLM request, locally.

Finding the latest release for your operating system…

Or install with a package manager
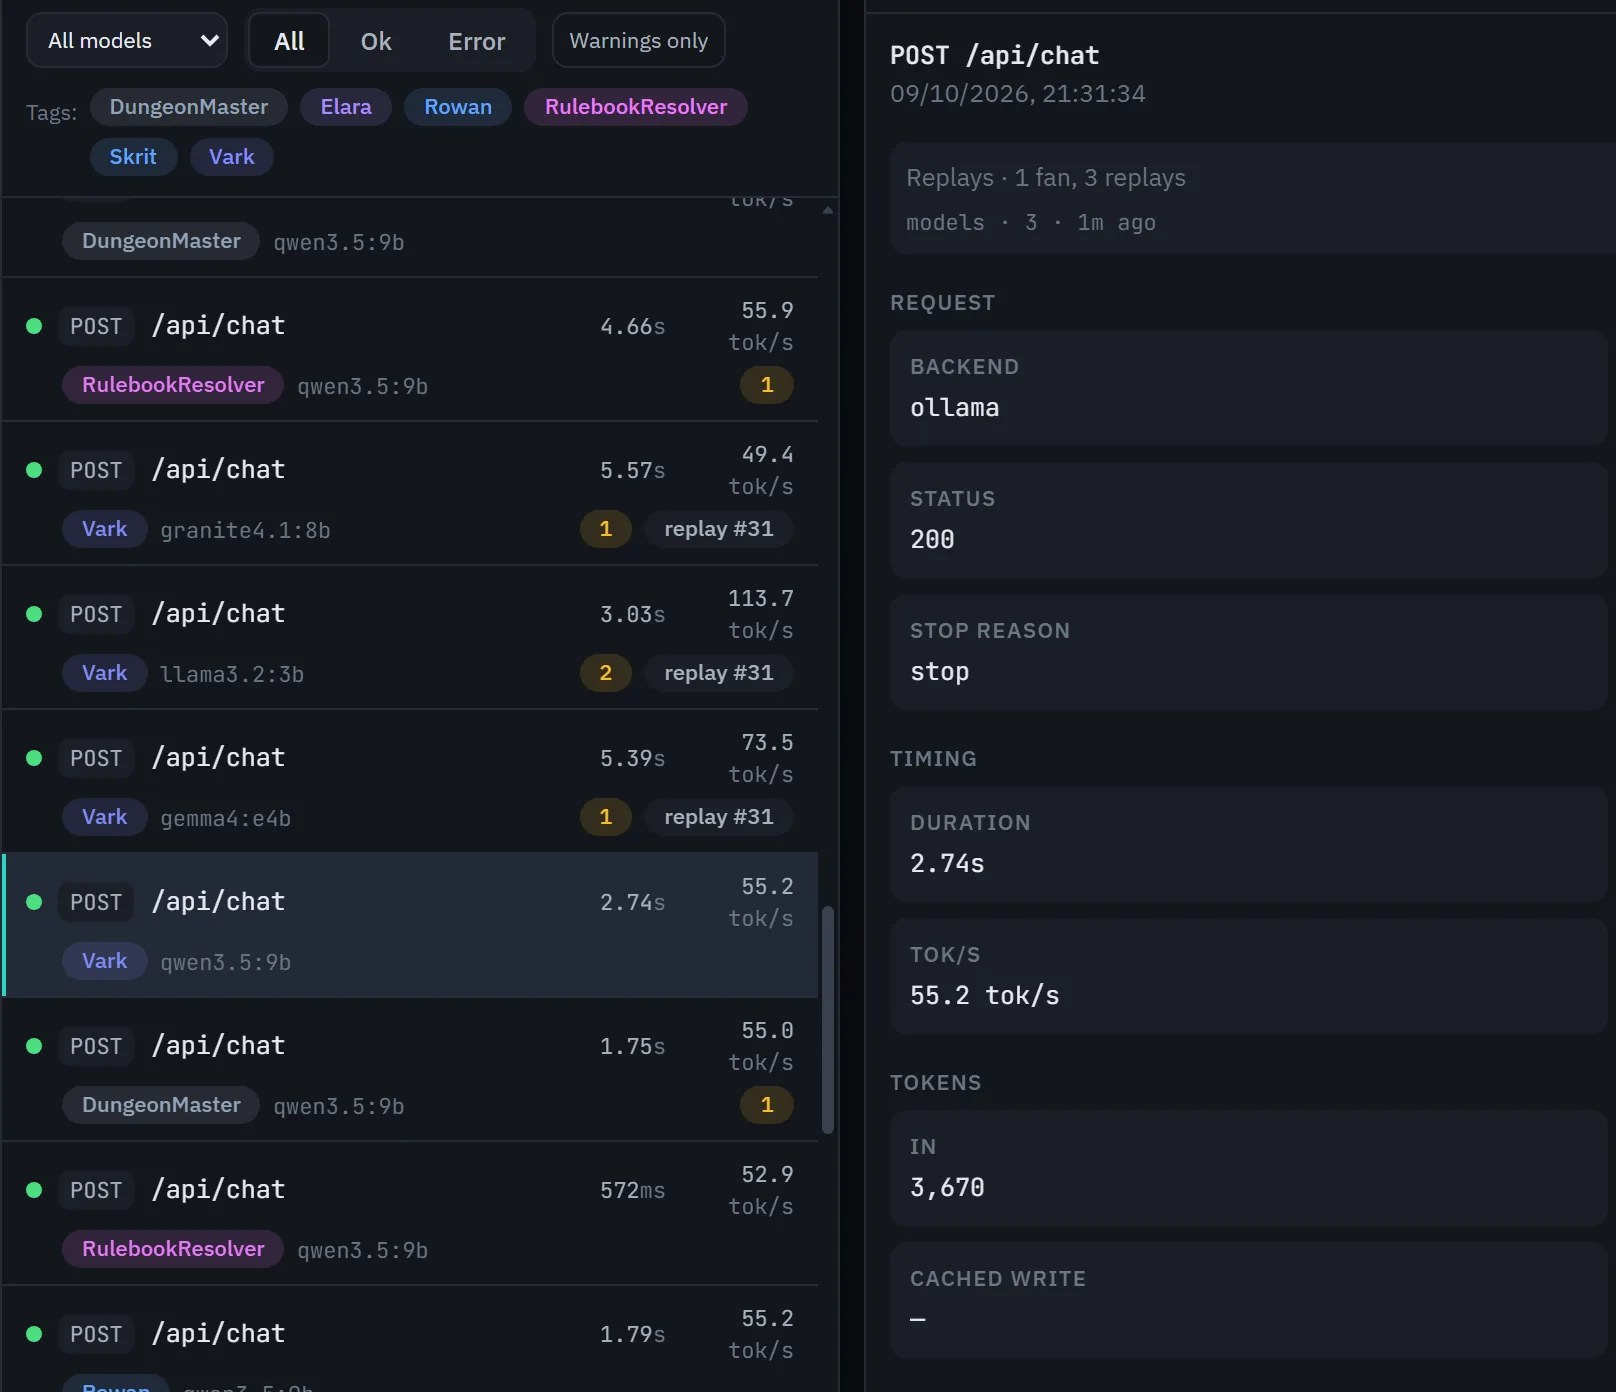
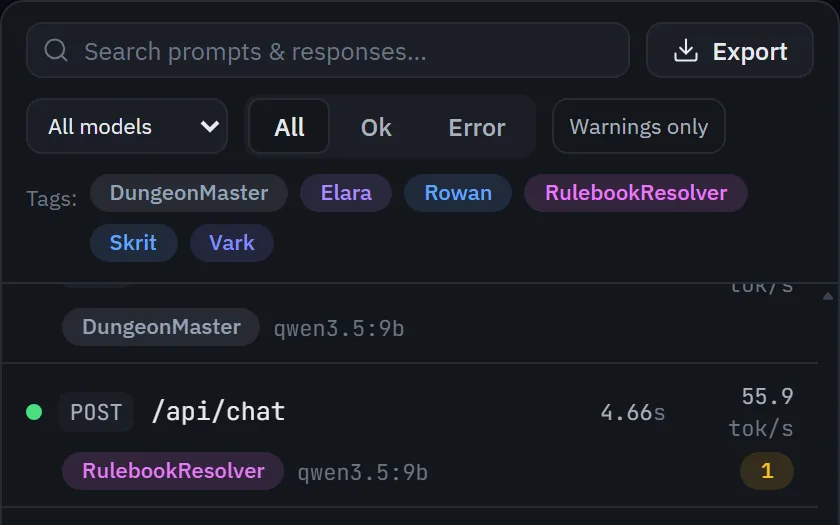
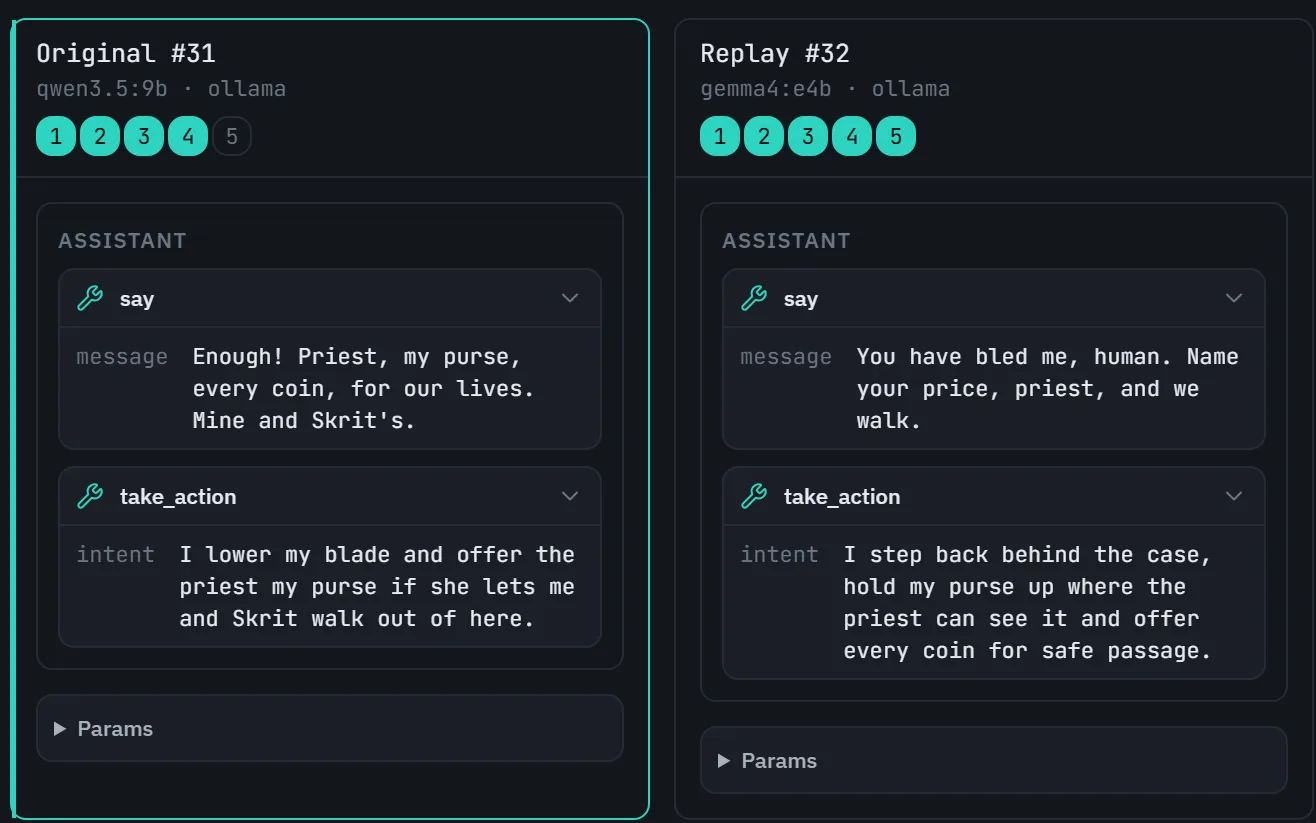
vessel's History view: a list of captured POST /api/chat requests, each tagged with the agent that sent it (DungeonMaster, Vark, RulebookResolver), beside one request's backend, model, timing and token counts

What vessel does with each request

vessel sits between your LLM clients and any backend: Ollama, OpenAI, Anthropic, or anything compatible.

Drop-in capture

Change one base URL. Every request and response, streamed or not, captured byte-for-byte with timing, TTFT, and token counts. Unknown traffic passes through untouched.

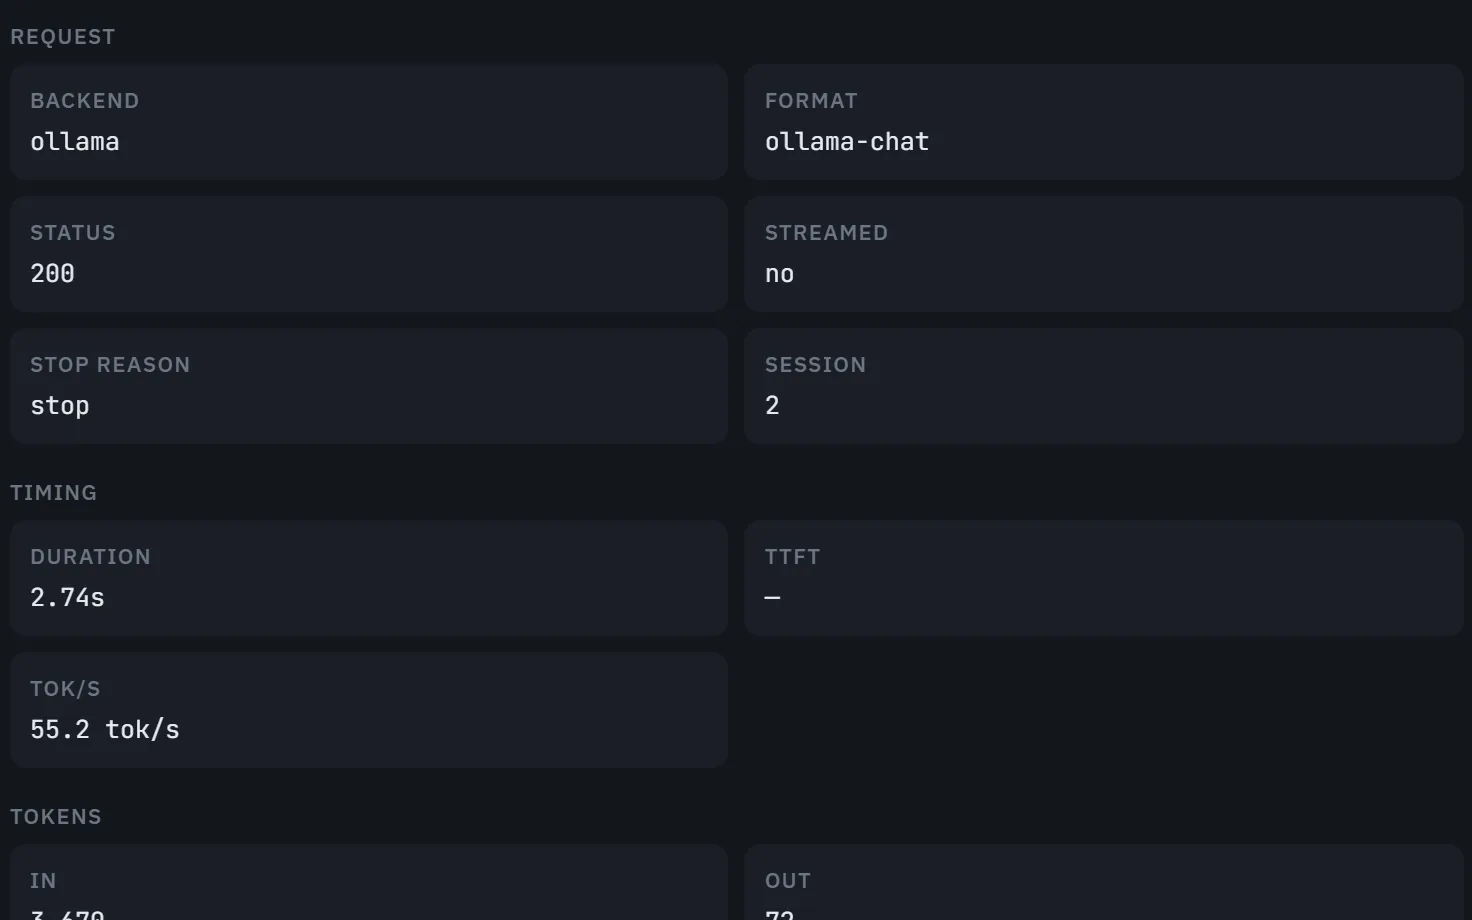
A captured request's overview: backend ollama, format ollama-chat, status 200, not streamed, stop reason stop, duration 2.74s and 55.2 tok/s

How Vessel is different

Vessel is a developer tool in the Fiddler / Wireshark family: it watches the wire between your client and the model, and never touches the request.

Vessel vs Langfuse (and Helicone, Phoenix, LangSmith)

  • Application-level vs wire-level. They instrument your code with an SDK and show you spans; Vessel observes the HTTP and shows you bytes. No SDK, no language binding: anything with a base URL, including tools you didn’t write (Open WebUI, aider, Cline).
  • Language-neutral. Langfuse is Python/TypeScript SDKs; Vessel is one base URL from any language, or a header, or a path prefix.
  • Scope. They’re multi-user, hosted-or-self-hosted, with dashboards and evals for a team. Vessel is single-binary, single-user, local SQLite. If you need team dashboards and prompt management, use them; Vessel exports CSV/JSONL if you later want to feed one.
Vessel vs LiteLLM (and other gateways)

  • A gateway routes and transforms: load-balancing, key management, format translation, retries. Vessel deliberately forwards byte-for-byte and never mutates. Different job, and they stack: put Vessel in front of LiteLLM to see what the gateway actually sent.
  • If your question is “what did my agent send?”, a gateway’s logs are one more layer between you and the answer.

Vessel vs mitmproxy / Charles / Proxyman

  • They’re general HTTP interceptors: you get raw JSON and streaming chunks, and you do the parsing. Vessel speaks the three wire formats natively: it reassembles the stream, counts tokens (exact when the backend reports them), measures TTFT, flags cold loads and truncations, and lets you replay and compare. Wireshark has dissectors; this is the LLM dissector.
  • No certificate install, no MITM: Vessel is a reverse proxy the client is pointed at.

Vessel vs “just log it in my code”

  • Works before you’ve written any code, and for code that isn’t yours.
  • Sees what actually went on the wire after the SDK’s defaults, retries, and transformations. That answers the “is it my code or the model?” question, which logging inside the code can’t.

Ask your AI about it

A built-in read-only MCP server lets Claude Code, or any MCP client, search and inspect your captured traffic directly.

“Why did my agent stall?” is now a question you can just ask.

Frequently asked questions

Does it change my requests?

No. Byte-for-byte, with only X-Vessel-* headers stripped. injectStreamUsage is the single opt-in exception, and it’s flagged on the row.

Where does the data go?

A SQLite file next to the config. Captured traffic is stored only on your machine; prompts are forwarded only to the model providers you configure. Auth headers are redacted at rest and keys are never stored.

Which backends?

Ollama native, any OpenAI-compatible server (LM Studio, llama.cpp, vLLM, OpenRouter, the OpenAI API itself), and Anthropic Messages. Unknown formats pass through and are stored raw.

Install with a package manager

One small binary. No account.

  • Homebrew for macOS (Apple Silicon) and Linux
    brew trust spenceclark/tap && brew install spenceclark/tap/vessel
  • winget for Windows
    winget install spenceclark.Vessel
  • Scoop for Windows
    scoop bucket add spenceclark https://github.com/spenceclark/scoop-bucket && scoop install vessel
Quickstart
OLLAMA_HOST=127.0.0.1:4550 ollama run llama3.2 # or any SDK: base_url = "http://127.0.0.1:4550/b/openai/v1"
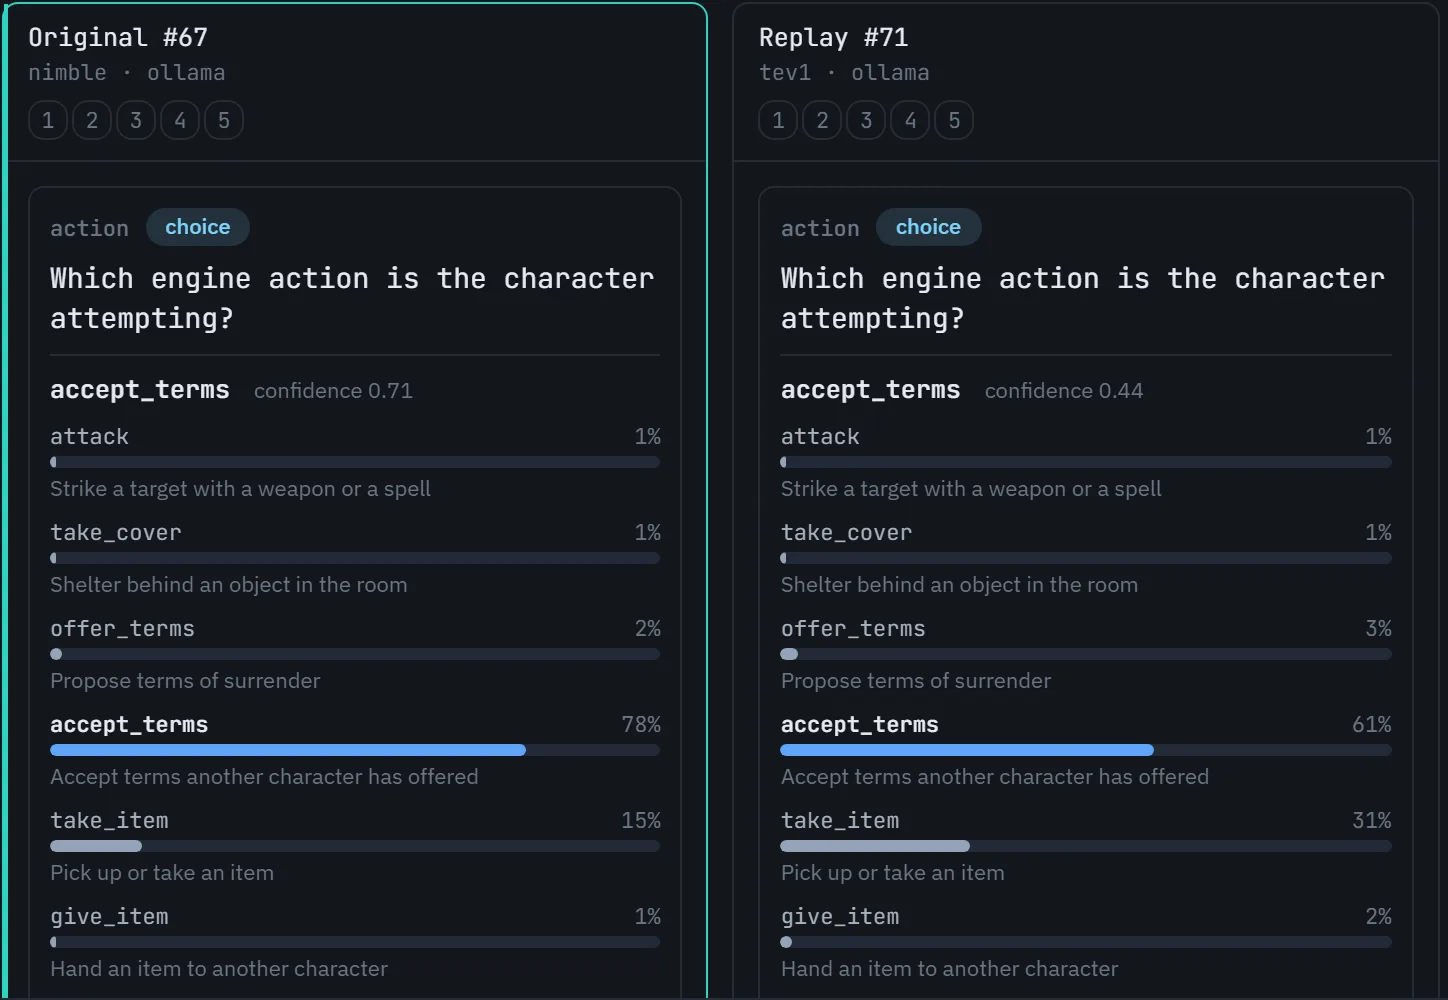
Original #67 on nimble beside Replay #71 on tev1, both choosing accept_terms, at 78% and 61%, with every other action's probability below